A few years before the advent of gpt-3, a colleague introduced me to an entrepreneur who had a problem he wanted to solve. He ran a “human supermarket shelf supervisors” business where each supervisor visited many supermarkets q day in order to check whether some products of a target brand were being “optimally presented” on the shelves.
Their job was to go to each supermarket, find the right shelves, take one or more pictures to each shelf and then upload the pictures to an app along with some data: how many spaces does the product occupied on a shelf and whether there were empty spaces at the front and how many. This process presented two issues, the time it took and human errors like bad pictures or wrong annotations.
The entrepreneur’s idea was to partially solve the time issue and the annotations issue. He knew I was working in “AI” at the moment so we talked about the problem, I was able to get access to some pictures and the data extracted of them in order to get an idea of the difficulty of this problem. The next time we talked I gave him my conclusion: “this is not possible unless you deploy many monies to hire a team to do it”. That was the end of the conversation, in Argentina the salaries in that year were very low so it was cheaper to still pay humans instead of building that kind of technology.
And that brings us to today, I’m working on several products where I need to check whether the newest LLMs finally crack some challenges so, with the help of my friend Claude, I built tinybenchmarks, a project to quickly run a one off test of a given task and check if some LLMs can solve it correctly.
This problem came to mind while I was thinking about interesting problems outside my current focus (I’ll share them soon) to start testing the tinybenchmarks project, in the next section I’ll share the results.
The supermarket shelf tiny benchmark
I used tinybenchmarks to check how good are some current LLM models (OpenAI family for now) when they need to do shelf supervision work, the chosen models were: gpt-6-astra, gpt-6.1-sol, gpt-6-luna and gpt-4.1.
I’ve picked 3 photos from argentinian supermarkets available online and created five tasks for the models to accomplish.
Let’s see them case by case:
Case 1: Facings of Ala sachets
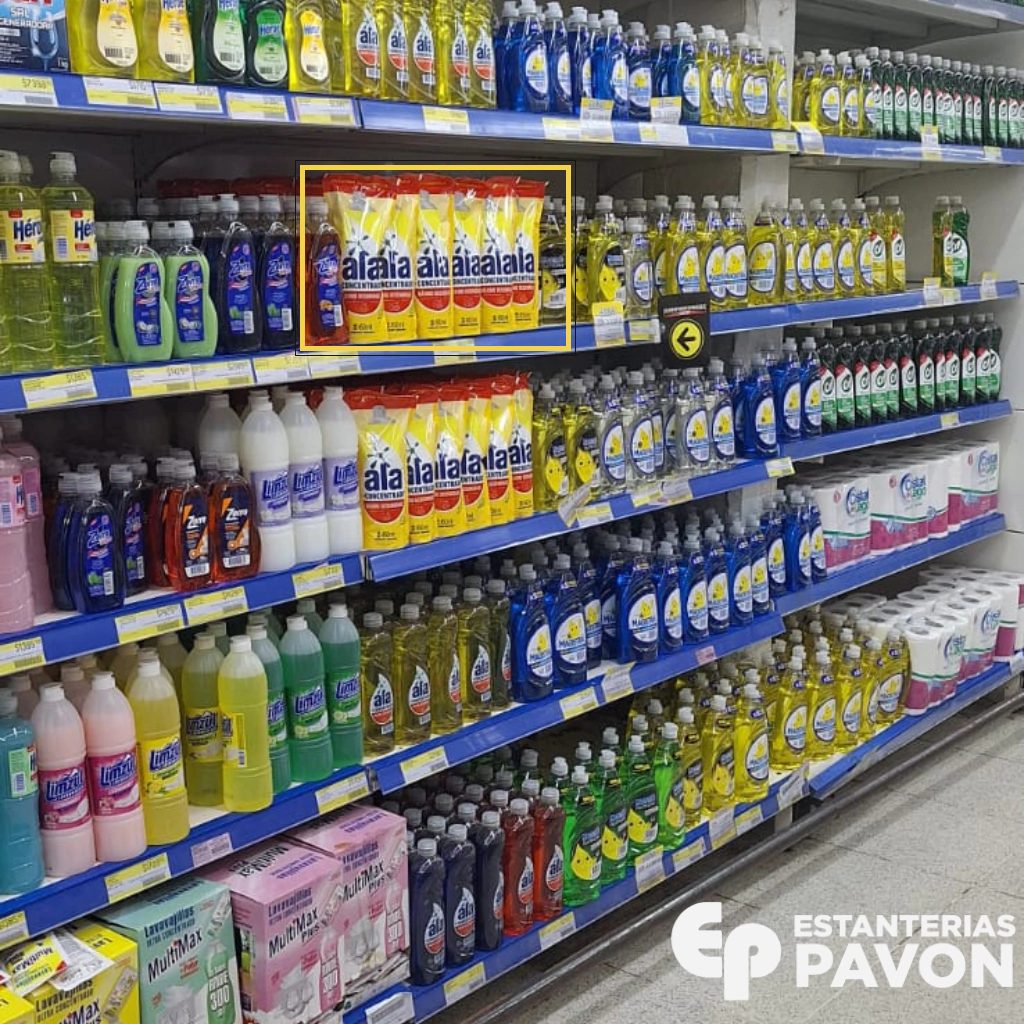
How many facings of the yellow “Ala concentrado” sachets are on the second shelf from the top?
Expected: 6
| Model | Run 1 | Run 2 | Run 3 |
|---|---|---|---|
gpt-6-astra | ✅ 6 | ✅ 6 | ✅ 6 |
gpt-6.1-sol | ✅ 6 | ✅ 6 | ✅ 6 |
gpt-6-luna | ❌ 7 | ✅ 6 | ❌ 7 |
gpt-4.1 | ❌ 5 | ✅ 6 | ✅ 6 |
Case 2: Gaps on a detergent shelf
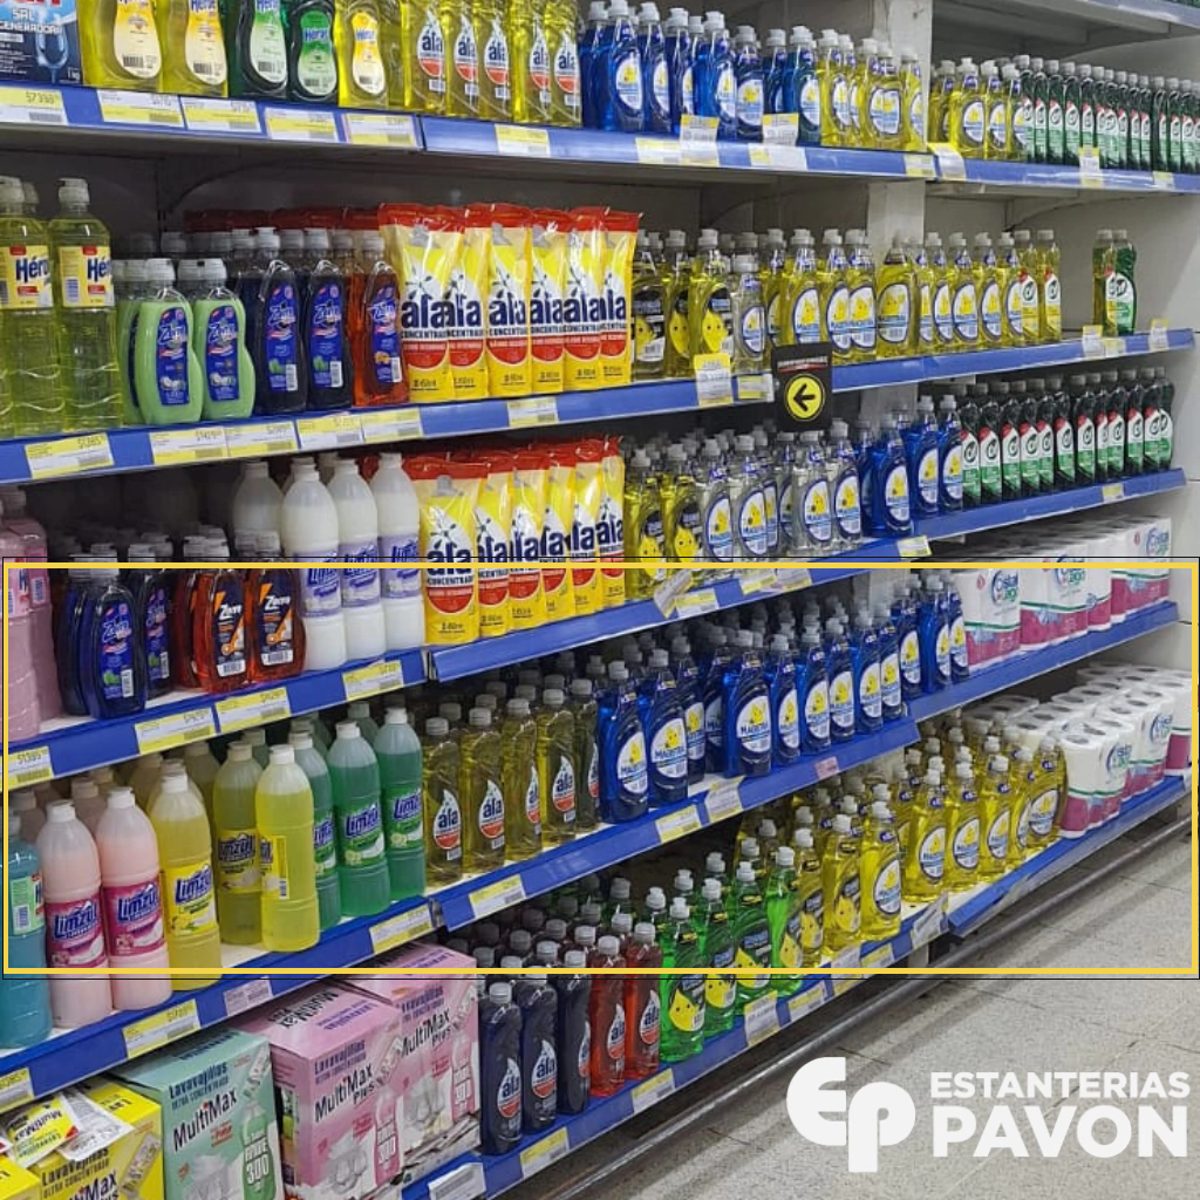
On the shelf with the large yellow “Limzul” bottles at the left end and the blue “Magistral” bottles, count the empty facings, split into yellow Limzul, blue Magistral and anything else.
Expected: 2 (1 Limzul · 1 Magistral · 0 other)
| Model | Run 1 | Run 2 | Run 3 |
|---|---|---|---|
gpt-6-astra | ✅ 2 (1 Lim · 1 Mag) | ❌ 3 (1 Lim · 2 Mag) | ✅ 2 (1 Lim · 1 Mag) |
gpt-6.1-sol | ✅ 2 (1 Lim · 1 Mag) | ✅ 2 (1 Lim · 1 Mag) | ✅ 2 (1 Lim · 1 Mag) |
gpt-6-luna | ❌ 1 (1 Mag) | ❌ 0 | ❌ 0 |
gpt-4.1 | ❌ 1 (1 Mag) | ✅ 2 (1 Lim · 1 Mag) | ❌ 1 (1 Mag) |
Case 3: Facings of Gallo Largo rice
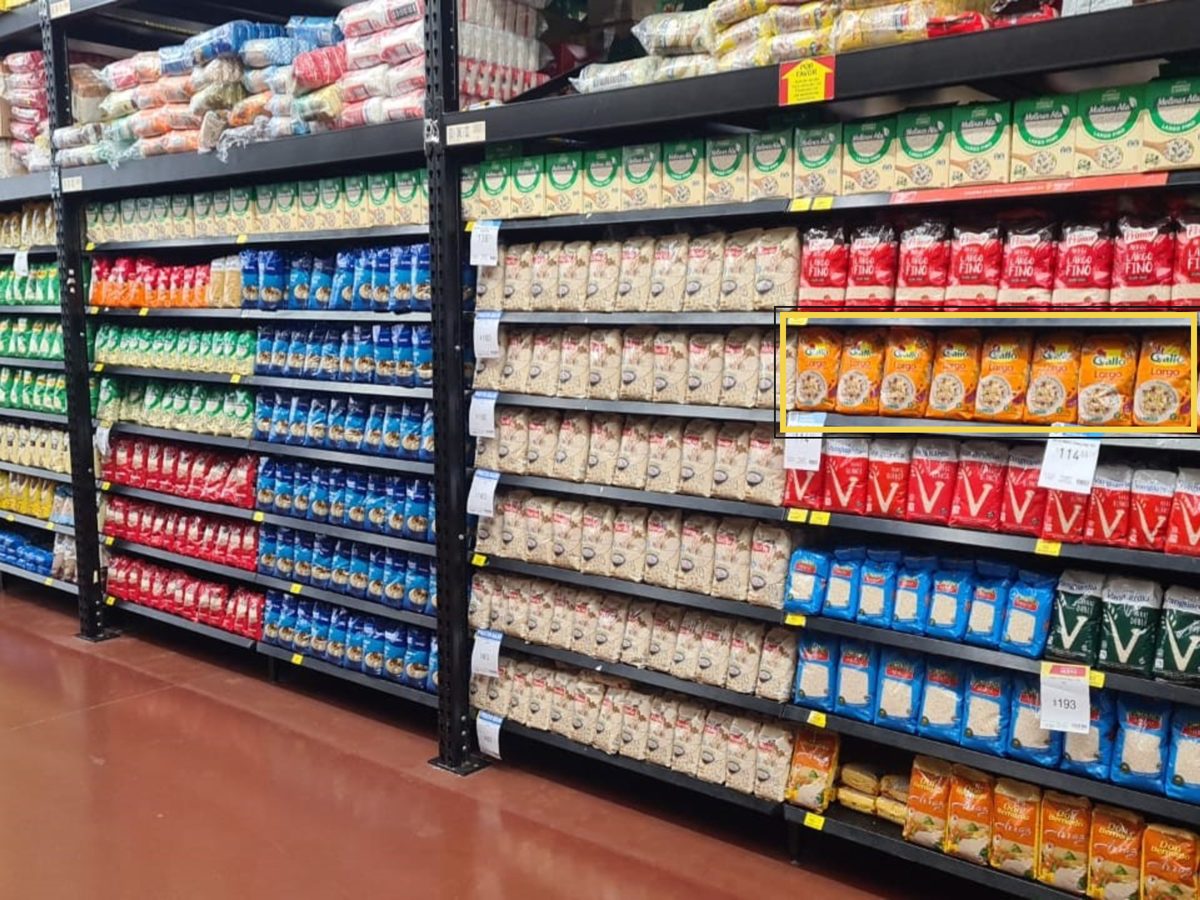
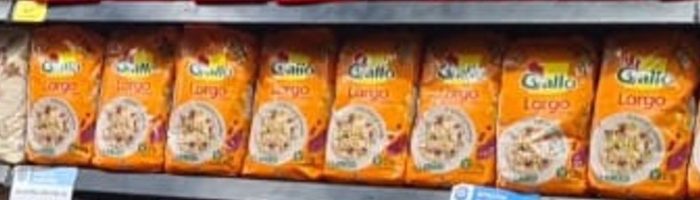
How many facings of “Gallo Largo” rice are there? Count only bags whose logo is visible; ignore the bag cut off at the right edge.
Expected: 8
| Model | Run 1 | Run 2 | Run 3 |
|---|---|---|---|
gpt-6-astra | ✅ 8 | ✅ 8 | ✅ 8 |
gpt-6.1-sol | ✅ 8 | ✅ 8 | ✅ 8 |
gpt-6-luna | ✅ 8 | ✅ 8 | ❌ 9 |
gpt-4.1 | ❌ 5 | ❌ 5 | ❌ 6 |
Case 4: Bags placed backwards
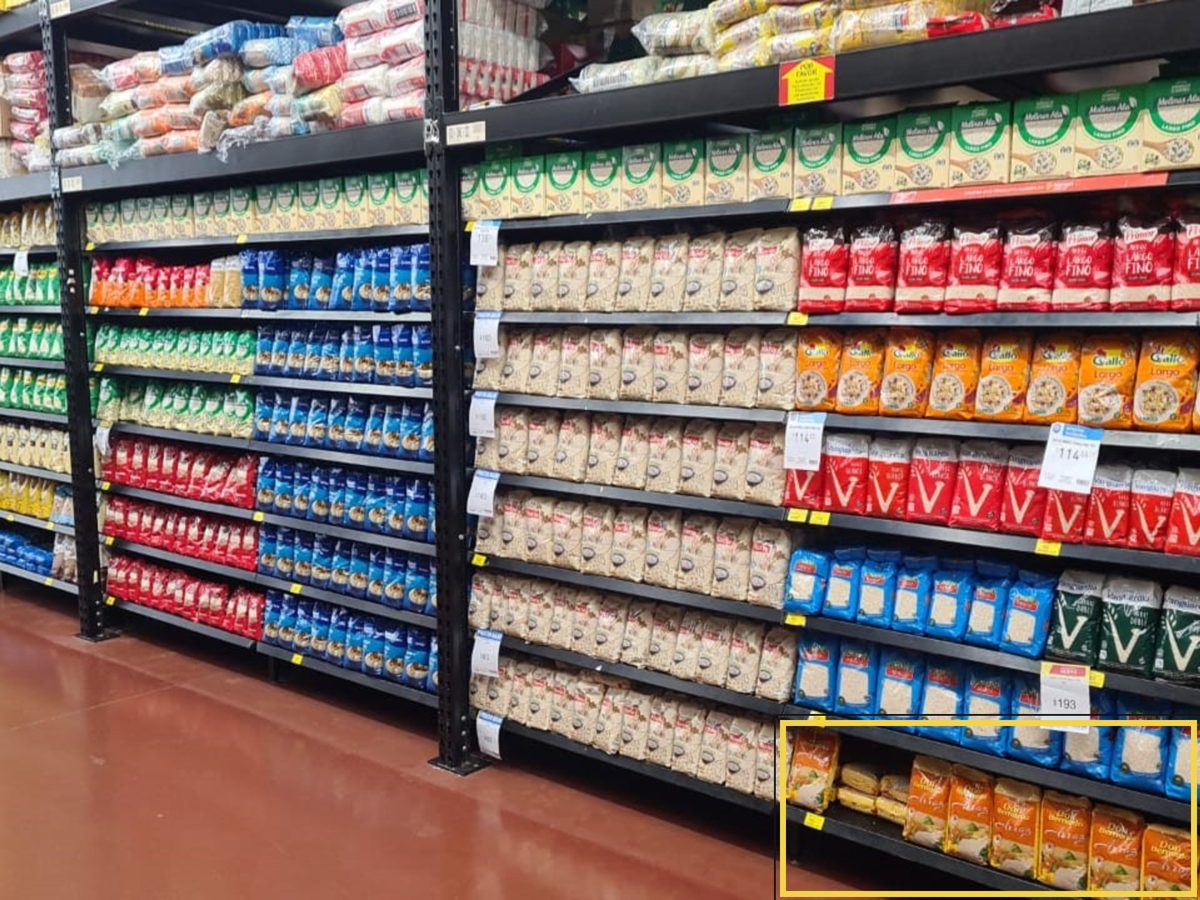
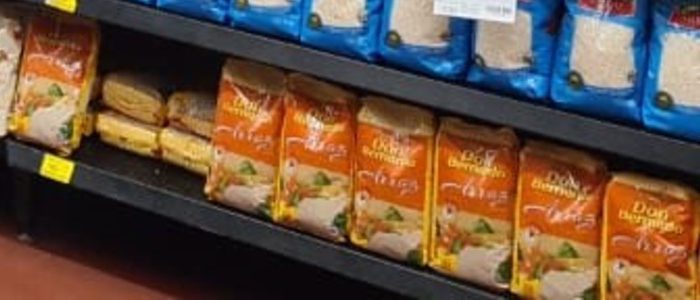
Count the facings that need restocking. A bag placed backwards also counts as a missing facing. Classify each gap by the product that should be there.
Expected: 2 (2 Don Bernardo · 0 other)
| Model | Run 1 | Run 2 | Run 3 |
|---|---|---|---|
gpt-6-astra | ✅ 2 (2 DB) | ✅ 2 (2 DB) | ✅ 2 (2 DB) |
gpt-6.1-sol | ✅ 2 (2 DB) | ✅ 2 (2 DB) | ✅ 2 (2 DB) |
gpt-6-luna | ❌ 3 (3 DB) | ❌ 3 (3 DB) | ❌ 3 (3 DB) |
gpt-4.1 | ❌ 5 (4 DB · 1 other) | ❌ 3 (2 DB · 1 other) | ❌ 5 (3 DB · 2 other) |
Case 5: The missing top layer
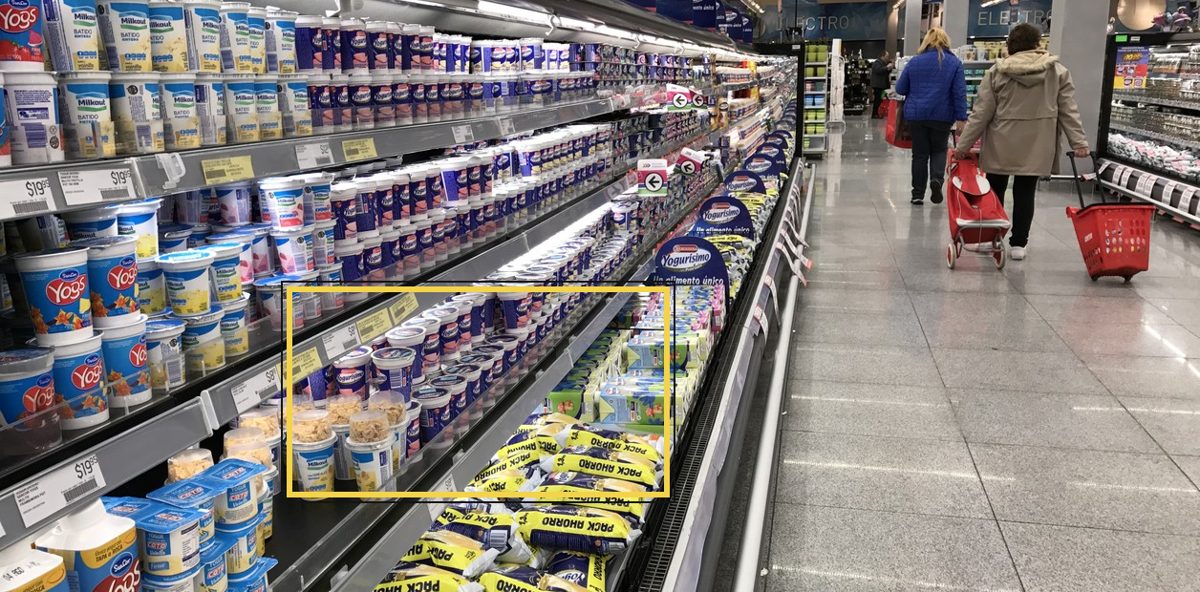
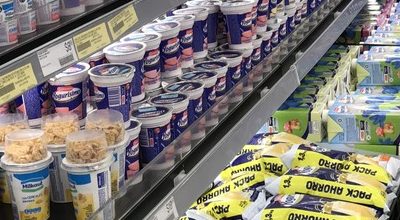
The strawberry “Yogurísimo” cups are stacked two high. How many cups need restocking in the top layer?
Expected: 6
| Model | Run 1 | Run 2 | Run 3 |
|---|---|---|---|
gpt-6-astra | ❌ 7 | ❌ 7 | ❌ 7 |
gpt-6.1-sol | ❌ 7 | ✅ 6 | ❌ 8 |
gpt-6-luna | ❌ 3 | ❌ 3 | ❌ 4 |
gpt-4.1 | ❌ 4 | ❌ 2 | ❌ 3 |
The results
| Model | Facings error ↓ | Facings exact | Gap count error ↓ | Gap count exact | Gaps by product | Cost per run |
|---|---|---|---|---|---|---|
gpt-6-astra | 0.00 | 100% | 0.44 | 56% | 80% | $1.15 |
gpt-6.1-sol | 0.00 | 100% | 0.33 | 78% | 89% | $0.24 |
gpt-6-luna | 0.50 | 50% | 1.78 | 0% | 48% | $0.02 |
gpt-4.1 | 1.50 | 33% | 2.00 | 11% | 48% | — |
Errors are the mean absolute difference from the right count. “Gaps by product” is the share of products whose gap count was right. Means over 3 runs of each case. The three GPT-6 models ran with reasoning_effort: high; gpt-4.1 doesn’t reason. Cost is the whole run per model (15 calls) at list prices; gpt-4.1’s price isn’t included.
Conclusion
Back then the problem was the cost: building this would have meant hiring a team, and humans were cheaper. Today the cost is partly gone. Running all five tasks with gpt-6.1-sol costs about eight cents so I don’t think that would be a big issue to take it into consideration.
What’s still missing is reliability. The two best models count facings perfectly, but that’s the easy half of the job. The point of auditing a shelf is finding what needs restocking, and there even the best models get the gap count wrong in one or two answers out of every four or five. Nobody reliably counted the missing layer of yogurts. A supervisor who missed one gap out of every four or five wouldn’t keep the job.
So, not yet. The models could already help, for example by counting facings and flagging photos for a human to check, but they can’t replace the person walking the aisles. This is five cases on three photos, so take it as a first look, not a final answer. I’ll keep adding harder cases and re-run it when new models come out.
Run it yourself
The benchmark is already available in tinybenchmarks if you’d like to take a look.
Leave a Reply